Last updated: October 20, 2026 · Prices checked against Alibaba Cloud Model Studio's model pages, the LiteLLM price file and Oxyy's live pricing pages on this date. Qwen prices change by region and promotion, so confirm in your Model Studio console before you commit.
Disclosure: This guide is published by the Oxyy.ai team. Qwen prices below are Alibaba's own list prices.
Quick answer: On Alibaba Cloud Model Studio's International scope, Qwen3.8-Max costs $2.00 per 1M input tokens and $6.00 per 1M output tokens. Qwen3.7-Plus costs $0.40 / $1.60 for prompts up to 256K tokens, and Qwen3.8-Flash costs $0.15 / $0.47. Qwen3-Coder-Plus was retired on October 10, 2026; Alibaba moved it to Qwen3.7-Plus. The cheapest third-party host for Qwen3.8-Max is DeepInfra at $1.65 / $4.95.
| Qwen model | Official input / output (per 1M, International) | Cheapest third-party (per 1M) | Cached input | Context |
|---|---|---|---|---|
Qwen3.8-Max (qwen3.8-max) | $2.00 / $6.00 | $1.65 / $4.95 (DeepInfra) | $0.25 (implicit) | ~992K |
Qwen3.7-Plus (qwen3.7-plus), ≤256K prompt | $0.40 / $1.60 | $0.282 / $1.128 (AIHubMix) | — | 1M |
| Qwen3.7-Plus, 256K–1M prompt | $1.20 / $4.80 | — | — | 1M |
Qwen3.8-Flash (qwen3.8-flash) | $0.15 / $0.47 | — | $0.016 | 1M |
Qwen3.7-Max (qwen3.7-max) | $2.50 / $7.50 (50% limited-time discount displayed) | — | — | — |
| Qwen3-Coder-Plus | Retired October 10, 2026 → migrate to Qwen3.7-Plus | |||
Key Takeaways
- Qwen3.8-Max is Alibaba's flagship: $2.00 / $6.00 per 1M tokens on the International scope, with a single price band up to its ~1M context.
- Price depends on deployment scope. The same Qwen3.8-Max lists at $1.65 / $4.95 on the Global scope.
- Qwen3-Coder-Plus is gone. It was part of Alibaba's October 10, 2026 deprecation wave, with Qwen3.7-Plus as the named replacement.
- Caching cuts input cost up to 90%. Explicit cache hits bill at 10% of input, implicit hits at 20%. Batch is 50% off, but batch and cache discounts don't stack.
- Rate limits differ by storefront. Model Studio and QwenCloud have published different limits for the same model.
- Cheaper alternatives exist. On Oxyy, GLM-5.3 costs $0.56 / $1.76 and DeepSeek-V4-Pro costs $0.264 / $0.792 per 1M tokens, both with 1M context.
How Qwen API Pricing Works
Qwen models are sold through Alibaba Cloud Model Studio (the DashScope API) and through QwenCloud, a Qwen-branded storefront that became generally available on March 31, 2026 and runs on the same DashScope infrastructure. You pay per token, with separate input and output rates.
Four things change the price you actually pay:
- Deployment scope. International, Global, China (Beijing) and US scopes have different prices, promotions and free quotas. Always record the scope with every price you quote.
- Tiered pricing. Some models price by the number of input tokens in a single request. Every token in the request is billed at the tier that request falls into. For example, a 300K-token prompt on Qwen3.7-Plus is billed entirely at the 256K–1M rate.
- Context caching. Explicit cache creation costs 125% of the input price; explicit cache hits cost 10%; implicit cache hits cost 20% on Model Studio.
- Batch. Batch calls cost 50% of the real-time price, but the batch and cache discounts can't be combined.
Qwen3.8-Max Pricing
Qwen3.8-Max is a 2.4-trillion-parameter MoE flagship that Alibaba positions for long-horizon coding and professional work. It has a ~992K-token context window and up to 131,072 output tokens.
| Billing item (per 1M tokens) | International scope | Global scope |
|---|---|---|
| Input | $2.00 | $1.65 |
| Output | $6.00 | $4.951 |
| Input (implicit cache) | $0.25 | $0.206 |
| Explicit cache creation | $2.50 | $2.063 |
| Explicit cache read | $0.17 | $0.137 |
Third-party hosts for Qwen3.8-Max (per 1M tokens, input / output): DeepInfra $1.65 / $4.951, SCX.ai $1.65 / $4.99, AIHubMix $1.69 / $5.07, and Fireworks, Novita and QwenCloud at $2.00 / $6.00. Note that some third-party hosts cap the context lower (DeepInfra and Fireworks list 256K).
Qwen3.7-Plus Pricing
Qwen3.7-Plus is the mid-tier model, and the official replacement for Qwen3-Coder-Plus. It uses tiered pricing:
| Input tokens per request | Input (per 1M) | Output (per 1M) |
|---|---|---|
| Up to 256K | $0.40 | $1.60 |
| 256K – 1M | $1.20 | $4.80 |
Third-party prices: AIHubMix $0.282 / $1.128, Together AI $0.32 / $1.28, Fireworks $0.40 / $1.60 (Fireworks caps context at 256K).
Qwen3.8-Flash Pricing
Qwen3.8-Flash is the low-cost, high-speed multimodal model with a 1M-token context. It supports both the OpenAI and Anthropic API formats, so it works with tools like Claude Code and Codex.
| Billing item (per 1M tokens) | International scope | Other scopes |
|---|---|---|
| Input | $0.15 | $0.113 |
| Output | $0.47 | $0.382 |
| Input (implicit cache) | $0.016 | $0.014 |
| Explicit cache creation | $0.20 | $0.177 |
| Explicit cache read | $0.016 | $0.014 |
Qwen3 Coder API Pricing: What Happened?
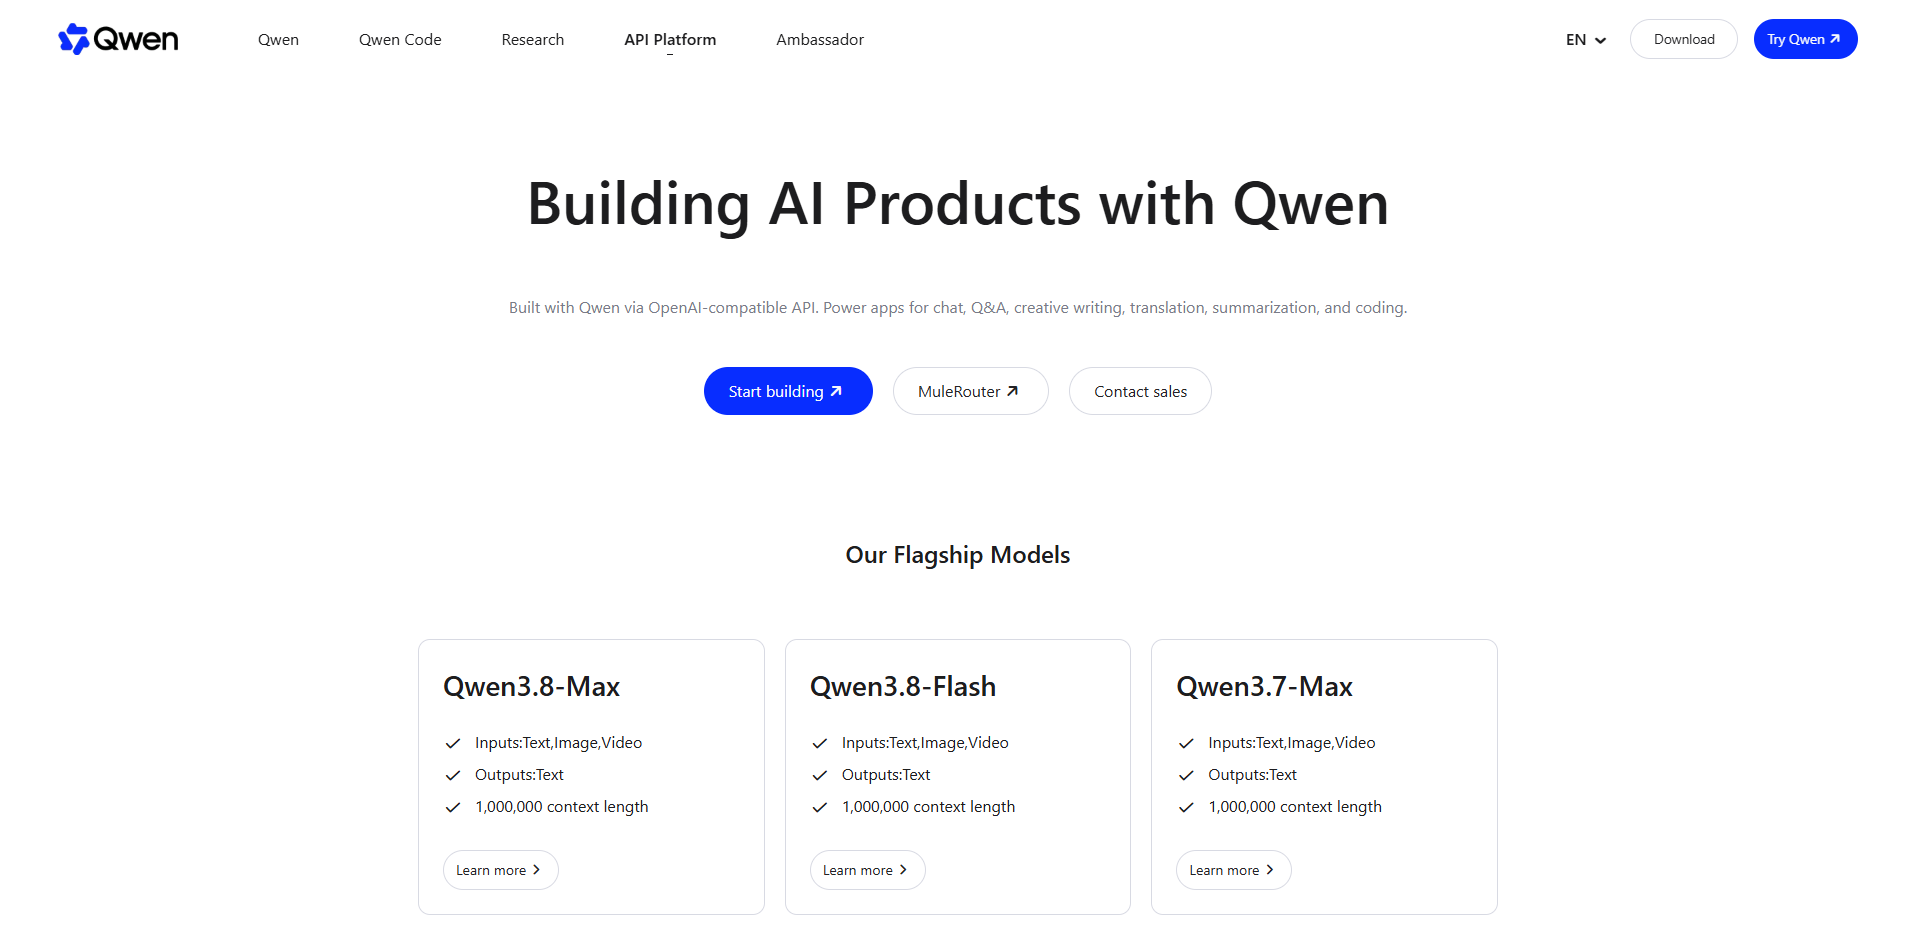
Qwen3-Coder-Plus was deprecated in Alibaba's October 10, 2026 wave, with Qwen3.7-Plus named as the migration target. The same wave moved Qwen3.6-Max-Preview and the Qwen3-Max line to Qwen3.7-Max.
Alibaba's policy is to give 30 days' notice for snapshot models and 3 months for mainline models, and throughput limits degrade progressively from the notice date. If you still call qwen3-coder-plus, switch now:
- Best like-for-like replacement:
qwen3.7-plus($0.40 / $1.60 up to 256K) - Cheapest Qwen option:
qwen3.8-flash($0.15 / $0.47) - Still listed:
qwen3-coder-flashremains in Model Studio's model list (~1M context, 65,536 max output)
Qwen API Rate Limits
Rate limits for the same model differ by storefront. At an August 2026 check, Qwen3.8-Max was documented at 600 RPM and 1M TPM on Model Studio International versus 15K RPM and 2M TPM on QwenCloud. Qwen3.8-Flash uses dynamic rate limiting on the International scope, where the TPM limit is tiered by your monthly Model Studio spend.
Watch out: pinning a dated snapshot can cut throughput sharply. Qwen3.7-Max snapshots were documented at 60 RPM, against 600 RPM on the rolling alias.
What Will Qwen Cost You? (Monthly Examples)
Example workload: 100M input tokens and 10M output tokens a month, no caching, International scope list prices.
| Model | Monthly cost |
|---|---|
| Qwen3.8-Max | $260.00 |
| Qwen3.8-Max on DeepInfra | $214.51 |
| Qwen3.7-Plus (prompts ≤256K) | $56.00 |
| Qwen3.8-Flash | $19.70 |
How to Call the Qwen API (OpenAI-Compatible)
from openai import OpenAI
import os

client = OpenAI(
    api_key=os.environ["DASHSCOPE_API_KEY"],
    base_url="https://dashscope-intl.aliyuncs.com/compatible-mode/v1",
)

resp = client.chat.completions.create(
    model="qwen3.8-max",
    messages=[{"role": "user", "content": "Write a Python function that parses ISO dates."}],
)
print(resp.choices[0].message.content)
Cheaper Alternatives to Qwen (Same Workload, 60% Off)
If you picked Qwen mainly for price, compare it with the open-weight coding and agent models on Oxyy.ai. Oxyy is a unified AI API gateway that currently charges 40% of the standard price on every rate (a 60% "Launch Promo"). Oxyy lists Qwen3 30B A3B (FP8) in its catalog, but its price isn't published yet, so the comparison below uses models Oxyy does price today.
| Model on Oxyy | Standard input / output | Oxyy input / output (per 1M) | Context | Cost for 100M in + 10M out |
|---|---|---|---|---|
| GLM-5.3 | $1.40 / $4.40 | $0.56 / $1.76 | 1.05M | $73.60 |
| DeepSeek-V4-Pro | $0.66 / $1.98 | $0.264 / $0.792 | 1M | $34.32 |
| Kimi K2.7 Code | $0.95 / $4.00 | $0.38 / $1.60 | 262K | $54.00 |
| GLM-5.3-Flash | $0.15 / $0.50 | $0.06 / $0.20 | — | $8.00 |
| DeepSeek-V4.1-Flash | $0.15 / $0.60 | $0.06 / $0.24 | — | $8.40 |
Oxyy prices from oxyy.ai/pricing and model pages, checked October 20, 2026. The 60% discount is a current launch promotion. Models differ in quality, so benchmark on your own tasks before switching.
Switching takes one line:
client = OpenAI(
    api_key=os.environ["OXYY_API_KEY"],
    base_url="https://api.oxyy.ai/v1",
)
resp = client.chat.completions.create(model="glm-5.3", messages=[...])
Why developers use Oxyy for open-weight models:
- One key for 170+ models from OpenAI, Anthropic, Google, xAI, DeepSeek, Z.ai, Moonshot and more
- No subscription, no monthly minimum, and credits never expire
- Free starting balance on signup, no card required
- OpenAI, Anthropic and Gemini SDKs work unchanged
- About 50 billion tokens and 5.8 million requests processed in the last 30 days (Oxyy About page)
Final Verdict
Qwen3.8-Max at $2 / $6 is competitively priced for a flagship, Qwen3.8-Flash at $0.15 / $0.47 is one of the cheapest 1M-context models from a major lab, and DeepInfra is the cheapest third-party host for Max. If you're still on Qwen3-Coder-Plus, migrate to Qwen3.7-Plus now. And if your main goal is the lowest bill for coding and agent work, test GLM-5.3 or DeepSeek-V4-Pro on Oxyy, where 100M input and 10M output tokens cost $73.60 and $34.32.
Try GLM-5.3 and DeepSeek-V4-Pro on a free Oxyy balance →
Related: GLM API pricing · DeepSeek API pricing · Kimi API pricing · Qwen on Oxyy
Frequently Asked Questions
How much does the Qwen API cost?
On Alibaba Cloud Model Studio's International scope, Qwen3.8-Max costs $2.00 input and $6.00 output per 1M tokens, Qwen3.7-Plus costs $0.40 / $1.60 for prompts up to 256K tokens, and Qwen3.8-Flash costs $0.15 / $0.47.
What is the cheapest Qwen model?
Qwen3.8-Flash is the cheapest current Qwen flagship-family model at $0.15 input and $0.47 output per 1M tokens on the International scope, with a 1M-token context window.
How much does Qwen3 Coder cost in 2026?
Qwen3-Coder-Plus was retired on October 10, 2026, and Alibaba named Qwen3.7-Plus as its replacement at $0.40 input and $1.60 output per 1M tokens for prompts up to 256K. Qwen3-Coder-Flash is still listed in Model Studio.
Is Qwen cheaper on third-party providers?
Sometimes. Qwen3.8-Max costs $1.65 / $4.951 per 1M tokens on DeepInfra versus $2.00 / $6.00 on Model Studio International. Some third-party hosts cap the context window lower.
Why do Qwen prices differ by region?
Alibaba prices each deployment scope separately. For example, Qwen3.8-Max is $2.00 / $6.00 on the International scope and $1.65 / $4.951 on the Global scope.
Does Qwen support prompt caching?
Yes. On Model Studio, explicit cache creation costs 125% of the input price, explicit cache hits cost 10% and implicit cache hits cost 20%.
Can I combine Qwen batch and cache discounts?
No. Batch calls cost 50% of the real-time price, but Alibaba says the batch and context cache discounts can't apply at the same time.
What are the Qwen API rate limits?
They vary by storefront and model. At an August 2026 check, Qwen3.8-Max was documented at 600 RPM and 1M TPM on Model Studio International and 15K RPM and 2M TPM on QwenCloud.
Is Qwen available on Oxyy?
Oxyy lists Qwen3 30B A3B (FP8), but its price isn't published yet. For low-cost coding and agent work, Oxyy offers GLM-5.3 at $0.56 / $1.76 and DeepSeek-V4-Pro at $0.264 / $0.792 per 1M tokens during its current 60% promotion.
Can I use the OpenAI SDK with Qwen?
Yes. Model Studio offers an OpenAI-compatible endpoint. Set the base URL to the compatible-mode URL for your region and use your DashScope API key.